Getting to Grips With Git
A reminder of the basics for the experienced, and a starting point for everyone else
Most of what I know about git I learned by getting it wrong in front of other people. That turns out to be a perfectly good way to learn it, but it is not a kind one, so here is the version I wish I had read first.
This post is aimed at two audiences at once. If you have never used git, it should give you the mental model before you start typing commands. If you use it every day, you may still find it useful to have the underlying model spelled out, because a surprising number of experienced developers drive git entirely from memorised incantations. I include myself in that for at least my first three years.
Git is not GitHub
First, the thing that confuses almost everyone at the start.
Git is a version control tool. It runs on your machine, it works with no network connection at all, and it has nothing to say about the internet.
GitHub is a company that hosts git repositories and builds a lot of useful things on top: pull requests, issues, code review, actions, permissions. GitLab, Bitbucket and Azure DevOps do much the same job. They are all optional. Git does not need any of them.
The distinction matters because a lot of what people call “git problems” are actually GitHub problems, and vice versa. Knowing which layer you are in saves a great deal of time.
The problem git actually solves
Imagine the head of maths at a secondary school, sitting down in August to write the department’s teaching plan for the year.
The first draft is simple enough:
# Teaching plan

## Year 7

## Year 8

## Year 9
At this point there is no problem to solve. There is one document, one author, and one copy. Version control would be pure overhead.
The problem arrives with version two.
Because version two is not written by one person on one afternoon. The Year 7 lead fills in her section. Someone else reworks Year 9 because the exam board changed the syllabus. The head of department edits the introduction. Two of them do this on the same Tuesday, on their own laptops, in a hurry.
Now the questions start. Which copy is the real one? Did the Year 9 rewrite make it into the version that went to the head teacher? Who removed the trip to the science museum, and when, and did they mean to? If we go back to how it looked in September, what exactly does “how it looked in September” mean?
Without a tool, the department solves this with filenames. teaching-plan-v2.docx. teaching-plan-v2-FINAL.docx. teaching-plan-v2-FINAL-jr-comments.docx. Everybody has seen this folder. Everybody has been burned by it.
Git is the tool that answers those questions properly. It gives you one document with a complete, ordered history of every version it has ever had, who made each change, and why. Software has exactly this problem, at a far greater scale, which is why git exists at all. But the problem is not really about code.
What git stores
Here is the bit most introductions get slightly wrong, and it is worth being precise about.
You will often hear that git stores the differences between versions. It does not, or at least not conceptually. Git stores snapshots.
Every time you commit, git records the complete state of every file at that moment. Think of it as photocopying the whole teaching plan, dating the copy, writing a note on the front about what changed, and putting it in a filing cabinet. The old copies stay exactly where they are. Nothing is overwritten.
That sounds hopelessly wasteful, and it would be, except that git is clever about storage: if a file has not changed since the last snapshot, git simply points the new snapshot at the existing copy rather than duplicating it. So the history is a series of complete states, stored efficiently.
Why does this matter to you? Because it explains git’s behaviour. Checking out an old version is fast and safe, because that version is sitting there whole, not reconstructed by unwinding a stack of edits. Branching is cheap, for the same reason. And when git shows you a diff, it is calculating that difference on the fly between two snapshots for your benefit, rather than reading it out of storage.
A single one of those snapshots, together with its author, timestamp, message and a pointer to the snapshot before it, is a commit. Commits are the unit of everything in git. A repository is, in essence, a chain of them.
The three places your work lives
The other thing worth understanding early is that git makes you move changes through three stages rather than one. This trips people up because most tools they have used have one stage: you save the file, and it is saved.
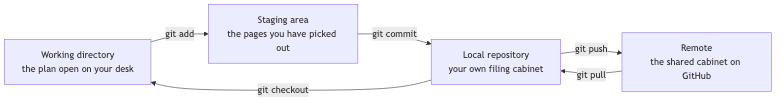
- The working directory is the folder on your machine. This is the teaching plan open on your desk with a pencil in your hand. Git is watching it, but it has not recorded anything yet.
- The staging area (sometimes called the index) is where you gather the changes you want in the next commit. This is you deciding which annotated pages go into the photocopier.
git addputs things here. - The repository is the filing cabinet: the permanent, ordered history.
git committakes what is staged and files it away as a snapshot.
The staging area is the stage people resent at first, and then come to appreciate. It exists so that a commit can be a deliberate, coherent unit of work rather than “everything I happened to touch this morning”. If you have fixed a typo and rewritten the Year 9 section in the same sitting, you can commit those separately, which makes the history far easier to read later.
A fourth box, the remote, is where GitHub reappears. A remote is just another copy of the repository, usually on a server, that you can push your commits to and pull other people’s commits from. It is optional, and it is the last thing to learn rather than the first.
Branches: two copies of the plan, recombined
Back to the maths department. The Year 9 syllabus rewrite is going to take three weeks and will look half-finished for most of that time. Nobody wants a half-finished Year 9 section in the plan that goes to the head teacher next Friday.
So you take a copy of the plan, work on the copy, and merge your finished work back in when it is ready. That is a branch.
In git a branch is remarkably lightweight: it is a named pointer to a commit. Creating one does not copy any files. When you make a commit on a branch, the pointer moves along to the new commit, and the branch you came from stays exactly where it was. Two people can work on two branches from the same starting point, and neither sees the other’s mess.
Merging is putting them back together. Git looks at the two branches and the commit they last had in common, works out what each side changed since then, and combines both sets of changes into a new commit.
Most of the time it manages this on its own, because the two sides changed different parts of the document. Year 7 and Year 9 do not overlap. Where git cannot decide is when both branches changed the same lines, and that is a merge conflict. Git stops, marks the disputed passages in the file, and asks you to choose. This is not git failing. It is git correctly refusing to guess which colleague was right about the science museum.
A worked sequence
Enough theory. Here is the whole cycle in one go, starting from an empty folder.
# Start a repository in the current folder
mkdir teaching-plan && cd teaching-plan
git init

# Create the first draft, then look at what git thinks
printf '# Teaching plan\n\n## Year 7\n\n## Year 8\n\n## Year 9\n' > plan.md
git status

# Stage it and commit the first snapshot
git add plan.md
git commit -m "First draft of the teaching plan"

# Branch off to do the Year 9 rewrite
git switch -c year-9-syllabus

# ...edit plan.md...
git add plan.md
git commit -m "Rewrite Year 9 for the new exam board syllabus"

# Go back to the main line and bring the work in
git switch main
git merge year-9-syllabus

# Read the history
git log --oneline --graph
A few notes on that:
git initcreates a hidden.gitfolder. That folder is the repository. Delete it and you have an ordinary folder again.git statusis the most useful command in git and the one beginners under-use. Run it constantly. It tells you which stage everything is in and usually suggests the command you want next.git switch -ccreates a branch and moves onto it. You will also seegit checkout -b, which does the same thing;switchis the newer, clearer spelling.git commit -mtakes the message inline. Write it for the colleague who reads it in six months, which is generally you. “Fix” is not a message.git log --oneline --graphdraws the history, branches and all. It is the fastest way to see what shape your repository is actually in.
What to learn next
This is the local half of git, and it is genuinely most of it. If you are comfortable with commits, branches and merges, you can work on your own indefinitely.
The next layer is collaboration, and it is worth learning as a separate topic rather than mixed in with the above:
- Remotes,
git clone,git pushandgit pull: how your filing cabinet stays in step with everyone else’s. - Pull requests (or merge requests): a GitHub feature, not a git one, where a branch is proposed for merging and colleagues review it first. This is where the version control tool turns into a working practice.
git diffandgit restore: seeing exactly what you have changed, and undoing it safely before it is committed.- Rebasing: an alternative to merging that rewrites history to be tidier. Useful, and quite capable of causing trouble on shared branches. Leave it until the rest is second nature.
Wrapping up
Git has a reputation for being hard, and its command line has earned a fair bit of that. But the model underneath is small: snapshots of the whole thing, arranged in a chain, with cheap named pointers you can work on separately and recombine. Almost every confusing thing git does makes sense once you hold that picture in your head.
If you take one habit away, make it git status. If you take two, make the second one small commits with honest messages. The maths department will thank you, and so will you, next August.