One Markdown File, Two Audiences: Building Web and Print Documents with Pandoc
Somebody will always ask for the PDF. Keeping a single Markdown source and building the web page and the printable document from it costs an afternoon, and saves you maintaining two documents for the rest of the project
The documentation looks lovely on the Pages site, and then someone in procurement, or audit, or the board, asks if they can have it as a PDF to read on the train. The reflex is to print the web page to PDF, which gives you a document with a navigation bar on every page and an interactive diagram that has turned into an empty rectangle. The second reflex is to paste it all into Word, which produces a perfectly decent document that starts to go out of date from the moment you save it. Of the two, the second is the worse habit, because it feels like a solution.
The better answer is to treat the Markdown as the source of truth and the web page and the PDF as two builds of it, in the same way that the Structurizr series treated the model as the source of truth and the diagrams as views. This post is the last piece of that arrangement: it takes one Markdown file and produces a web page and a print-ready PDF from it, each styled for its own medium, with the interactive Structurizr diagrams on the web and a set of static ones on paper. It does take some setting up, but you do it once, and after that “can I have a PDF?” becomes a command rather than a request.
The document we are building
I want a realistic document rather than a toy, so we’ll use the boat hire service from the Structurizr posts and write a short architecture overview for it. Here it is whole, and then we’ll unpack the unfamiliar parts:
---
title: Boat Hire Service, Architecture Overview
author: Brian Jones
date: 27 October 2026
---
# Architecture overview
The boat hire service takes bookings, checks that the hirer is entitled
to skipper a boat, and records the boat's condition when it comes back.
## The system at a glance
::: web-only
<iframe src="structurizr-site/index.html" width="100%" height="600"
title="Interactive C4 diagrams for the boat hire service"></iframe>
:::
::: print-only


:::
## Decisions
See the [decision register](https://example.org/decisions/) for the
reasoning behind each choice.
The block at the top, between the --- lines, is metadata that Pandoc (our converter, which we’ll get to) uses for the title page and the HTML <title>. The ::: fences are Pandoc’s way of wrapping a run of blocks in a div with a class, and that is the whole trick of the post: one section of the document is labelled web-only and another print-only, and each build keeps the one it wants.
One honest caveat before we go on. Those fences are Pandoc’s dialect, so this file will not render properly in kramdown or on github.com, where the ::: lines show up as stray text. That is fine if documents like this are built by Pandoc and published as finished HTML and PDF, and awkward if you also want Jekyll to process the same file.
In reality I avoid doing this, as much as I can, but where I have to I keep these documents in their own folder, outside anything Jekyll builds, and copy the output into the _site folder afterwards.
Choosing a tool: the small converters, and Pandoc
There are two broad families of tool for turning Markdown into something else. The first is the small converters: cmark-gfm, which is the reference C implementation of CommonMark with GitHub’s extensions, and the JavaScript pair marked and markdown-it, each of which comes with a command line wrapper. They do one job, which is turning Markdown into an HTML fragment, and they do it quickly and predictably. There is almost nothing to learn, and nothing to go wrong, which is a real virtue when the Markdown is a README.
They also stop where our requirements begin. A fragment is not a page, so you write the surrounding HTML yourself, along with the table of contents, the title block, and the cross-references. By default cmark-gfm also replaces raw HTML with a comment, which means our iframe vanishes unless we pass --unsafe, and the converters have no concept of a document that comes out differently for different audiences. None of that is a flaw, but it does mean the work lands in your build script.
A handful of tools go one step further and produce a PDF directly. md-to-pdf is the one I’d look at first: it renders the Markdown to HTML, opens it in headless Chromium, and prints it, so your stylesheet is ordinary CSS and the PDF looks like the browser’s idea of the page. It is the quickest route from a README to something you can email. What it lacks is the second half of our problem, because it has one output and no clean way to say that this paragraph is for the screen and that one is for paper.
The second family is Pandoc, which is better thought of as a document converter that happens to read Markdown. It reads a dozen or so input formats and writes several dozen, so the same source can become HTML, PDF, Word, EPUB or LaTeX. It generates the table of contents and the title block, handles citations and footnotes, and has a filter system that lets you rewrite the document between reading and writing, which is the feature we will lean on. The cost is size and a little ceremony: it is a large program with a lot of options, and its Markdown has extensions that the others don’t understand.
For a single README, use whichever small converter is already in your toolchain. For a document that has to be a web page and a PDF, with a table of contents, and that differs between the two, I’d reach for Pandoc, and everything below assumes it.
Building the web version
The simplest build is a single command:
pandoc architecture.md \
  --standalone --toc \
  --css web.css \
  --embed-resources \
  --metadata target=web \
  --lua-filter audience.lua \
  -o dist/architecture.html
--standalone produces a whole page rather than a fragment, --toc builds a table of contents from the headings, and --css links the stylesheet. --embed-resources folds the stylesheet and images into the one HTML file, which makes it easy to email or drop on a file share, though it does not embed an iframe’s target, so the Structurizr site still needs to sit alongside it. The last two options are ours: --metadata target=web sets a value that the filter can read, and --lua-filter names the filter that acts on it. We’ll write that shortly.
The web stylesheet is the one most of us already know how to write, and the Paletton post covered where its colours come from. It assumes a screen of unknown width and an unknown reader, so it makes the text column a comfortable measure, lets the layout flex, and uses a sticky contents list because scrolling is free and finding your place is not.
Styling for paper is a different job
It is tempting to assume print styling is the web stylesheet with a few things hidden, and I think most of us start there. In practice the two media disagree about enough basic things that they are better treated as separate stylesheets with a shared palette.
The first difference is that paper has a fixed size and the page break is part of your layout. You choose the size and margins once with @page, and then you spend your time stopping things from breaking in silly places. A heading stranded at the bottom of a page with its first paragraph on the next is the classic failure, and a diagram split across two sheets is the other. Both have small fixes:
@page {
  size: A4;
  margin: 2.2cm 2cm 2.5cm;

  @bottom-center {
    content: counter(page) " of " counter(pages);
    font-size: 9pt;
  }
}

h1, h2, h3 { break-after: avoid; }
figure, pre, blockquote { break-inside: avoid; }
Page numbers like these are generated by the print engine, which is the reason we’ll use WeasyPrint rather than a browser in a moment. The second difference is the unit. On the web, sizes are in rem and the reader’s browser settings win. On paper there is a physical size, so type is set in points (11pt body text is a sensible default) and margins in centimetres, which saves you from guessing how large 1.5rem turns out to be on an A4 sheet.
The third difference is what to do with things that only work on a screen. A link is a clickable underline online and, on paper, a blue word that goes nowhere. The usual fix is to print the address after the link, and to turn the table of contents entries into page references, which is something a screen has no use for:
a[href^="http"]::after {
  content: " (" attr(href) ")";
  font-size: 0.85em;
  word-break: break-all;
}

#TOC a::after {
  content: " … " target-counter(attr(href), page);
}

pre { white-space: pre-wrap; }
The last rule is easy to miss. On screen, a long line of code scrolls sideways. On paper there is no sideways, so the line is simply cut off at the edge of the sheet unless you let it wrap.
The remaining differences are a matter of taste and of printers. I’d use a serif face for the body in print, because it reads better at length on paper, and keep a sans-serif for headings so that the two documents are recognisably related. Backgrounds and large blocks of colour get dropped, since they cost toner and photocopy as grey slabs, and the accent colour from the palette is kept for rules and headings, where it still shows up in greyscale as a darker line.
Changing the content, not just the styling
CSS can hide things, but it has a limit, and our iframe finds it. If web-only is hidden with display: none in the print stylesheet, the browser or print engine still has to parse the iframe, and some engines will go and fetch whatever it points at. The cleaner approach is to remove the content from the document before it is ever rendered, and this is what the Lua filter is for. The whole thing is short:
-- audience.lua: keep web-only or print-only blocks, depending on target
function Pandoc(doc)
  local target = doc.meta.target
      and pandoc.utils.stringify(doc.meta.target) or "web"

  doc.blocks = doc.blocks:walk({
    Div = function(div)
      if div.classes:includes("web-only") and target ~= "web" then
        return {}
      elseif div.classes:includes("print-only") and target ~= "print" then
        return {}
      end
    end
  })
  return doc
end
The filter reads the target value we passed on the command line, defaulting to web, and walks every div in the document. A web-only div is deleted unless the target is the web, and a print-only div is deleted unless the target is print. A div with neither class falls through unchanged. I went for a metadata value rather than testing the output format because the PDF is produced by writing HTML and then printing it, so as far as the filter can tell the web page and the PDF are both HTML.
The same mechanism covers more than diagrams. Anywhere that the screen offers something the paper can’t, such as a video, a live dashboard, or an “expand all” control, you can write the paper’s alternative beside it. A sentence like “see the interactive version at the address below” in a print-only block is often all the PDF needs.
Building the PDF
For the PDF, Pandoc writes an HTML document and hands it to a PDF engine. The choice of engine matters more than it appears. A LaTeX engine such as xelatex gives the best typography, and a large install and a different language for styling. A browser-based engine such as wkhtmltopdf gives you ordinary CSS, but its page furniture is limited. WeasyPrint sits between them: it is a Python program that renders HTML and CSS specifically for paged media, and it understands @page, running page numbers and target-counter, which is why the stylesheet above works. It does not run JavaScript, so there is no point asking it to draw an iframe, which is another reason the content swap above is not optional.
pandoc architecture.md \
  --standalone --toc \
  --css print.css \
  --metadata target=print \
  --lua-filter audience.lua \
  --pdf-engine=weasyprint \
  -o dist/architecture.pdf
That is the same command as before with three changes: the stylesheet, the target, and the engine. Here is how the pieces fit together, from one source to two outputs:
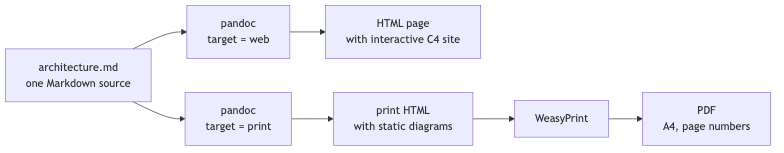
I ran all of this on macOS with Pandoc 3.12.1 and WeasyPrint 70.0, using the files shown above. The web build produces a single HTML file containing the iframe and none of the diagram images. The print build produces a two-page A4 PDF with all four diagrams, “1 of 2” page numbers in the footer, a contents list carrying page references, and the address printed after the one external link. Neither output contains the other’s content.
The images the print version needs come from the Mermaid exports the series already produces, and the iframe’s target is the structurizr-site folder that make structurizr-site builds, as described in the containers post. The diagrams in the PDF are static pictures of the same model that drives the interactive site, so the two versions can’t disagree about what the architecture is.
Wiring it together
Typing those commands by hand will last about a week. There are three places I’d put them, and they suit different situations.
A Makefile
If you already have a Makefile, as this series does, the documents become two more pattern rules, and Make’s feature of rebuilding only what has changed is exactly what you want:
DOCS := $(wildcard docs/*.md)
HTML := $(patsubst docs/%.md,dist/%.html,$(DOCS))
PDF  := $(patsubst docs/%.md,dist/%.pdf,$(DOCS))

PANDOC_COMMON := --standalone --toc --lua-filter docs/audience.lua

dist/%.html: docs/%.md docs/web.css docs/audience.lua
	@mkdir -p dist
	pandoc $< $(PANDOC_COMMON) --css docs/web.css \
	  --embed-resources --metadata target=web -o $@

dist/%.pdf: docs/%.md docs/print.css docs/audience.lua
	@mkdir -p dist
	pandoc $< $(PANDOC_COMMON) --css docs/print.css \
	  --metadata target=print --pdf-engine=weasyprint -o $@

documents: $(HTML) $(PDF)
Because each output lists the stylesheet and the filter as prerequisites, changing the print CSS rebuilds the PDFs and leaves the web pages alone. I checked that by touching print.css and running make -n documents, which listed only the PDF. I wrote more about why pattern rules suit this kind of job in Makefiles - Still a Useful Tool.
A GitHub Actions workflow
The Makefile gets the documents built on your machine, and a pipeline gets them built every time, on a machine with nothing else on it. That matters more than it sounds, because a PDF that depends on which fonts happen to be installed on your laptop is a PDF nobody else can reproduce. The workflow installs the tools, calls the same make target, and publishes the results alongside the site:
name: Build documents

on:
  push:
    branches: [main]
    paths: ["docs/**"]

jobs:
  documents:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7

      - name: Install Pandoc and WeasyPrint
        run: |
          sudo apt-get update
          sudo apt-get install -y pandoc weasyprint

      - name: Build HTML and PDF
        run: make documents

      - uses: actions/upload-artifact@v4
        with:
          name: documents
          path: dist/
Distribution packages of Pandoc tend to lag behind the current release, and --embed-resources needs 2.19 or later. Keeping the workflow as a thin wrapper around make documents means the pipeline and your laptop can’t drift apart, since they run the same command. To publish the files with the rest of the site, copy dist/ into the Pages artifact in the deploy workflow from the Pages post, and link to the PDF from the page it belongs to.
A script that serves the downloads
Static files on Pages cover most cases, and I would stop there if I could. The case for a small server is that sometimes the PDF should not be public, or you want to know who downloaded it, or the file needs a sensible name rather than architecture.pdf. Here are two ways of offering the generated files for download, in the two languages I’d expect to find on a team. Both serve files that were built in advance, and neither runs Pandoc in response to a web request, since passing anything a visitor typed to a command line is a problem you do not need.
In Go, the standard library does nearly all of it:
package main

import (
	"log"
	"net/http"
	"path/filepath"
)

func main() {
	files := http.FileServer(http.Dir("dist"))

	http.HandleFunc("/downloads/", func(w http.ResponseWriter, r *http.Request) {
		name := filepath.Base(r.URL.Path) // only the file name goes into the header
		if filepath.Ext(name) == ".pdf" {
			w.Header().Set("Content-Disposition", `attachment; filename="`+name+`"`)
		}
		http.StripPrefix("/downloads/", files).ServeHTTP(w, r)
	})

	log.Fatal(http.ListenAndServe(":8080", nil))
}
The Content-Disposition header is what makes a browser save the PDF rather than open it, and http.FileServer already refuses paths that climb out of dist: requests for /downloads/../main.go and /downloads/..%2f..%2fMakefile returned a redirect to a path that 404s and a plain 404, while a missing file also gave 404. In Django, the same job is a view that looks the document up in a fixed list, so a request can never name a path of its own:
from django.http import FileResponse, Http404
from django.conf import settings

DOCUMENTS = {
    "architecture": "architecture.pdf",
    "decisions": "decisions.pdf",
}

def download(request, slug):
    filename = DOCUMENTS.get(slug)
    if filename is None:
        raise Http404
    path = settings.BASE_DIR / "dist" / filename
    if not path.is_file():
        raise Http404
    return FileResponse(open(path, "rb"), as_attachment=True, filename=filename)
The lookup table is doing the security work: a slug is either in it or it isn’t. The is_file() check earns its place too. My first version omitted it, and a slug that was in the table but hadn’t been built yet raised a FileNotFoundError and a 500 error instead of a 404. Where Django earns its place over Go is when the download sits behind a login, because decorating the view with login_required takes one line, and permission checks and an audit log are things a Django project tends to have already.
What this arrangement leaves you with
The result is a Markdown file in the repository, reviewed in pull requests like any other change, and two commands that turn it into the artefacts different readers want. The web version has the interactive diagrams and a sticky contents list. The PDF has page numbers, printed link addresses, and four diagrams that were generated from the same model as the interactive site. If the decision register or the model changes, the next build brings both versions up to date together.
There are things I haven’t solved. Pandoc’s Markdown is not quite everyone else’s Markdown, which is the price of the fenced divs, and I would not want to hide that from a team that expects github.com to render every file properly. WeasyPrint is also a stricter reader of CSS than a browser, so a layout that looks right in Chrome can need nudging before it prints right, and the first PDF is usually the one where you find that out. Both are small prices for not maintaining a Word copy of your architecture.
The same source can be built a third time without much more work. A Word document is -o architecture.docx and a word-only class away, which suits the colleague who insists on tracked changes, and it is a pleasant surprise to find that the filter doesn’t care how many audiences there are.